
juju notifies the other side of a relation when the text of a databag value changes. It’s a byte comparison, so when a charm writes an unordered collection (e.g. a set result) into a databag without sorting it first, the JSON comes out in a different order every time that code runs, even though nothing about the data changed.
The Ping-Pong situation
Picture 2 charms on either side of a relation, both doing this:
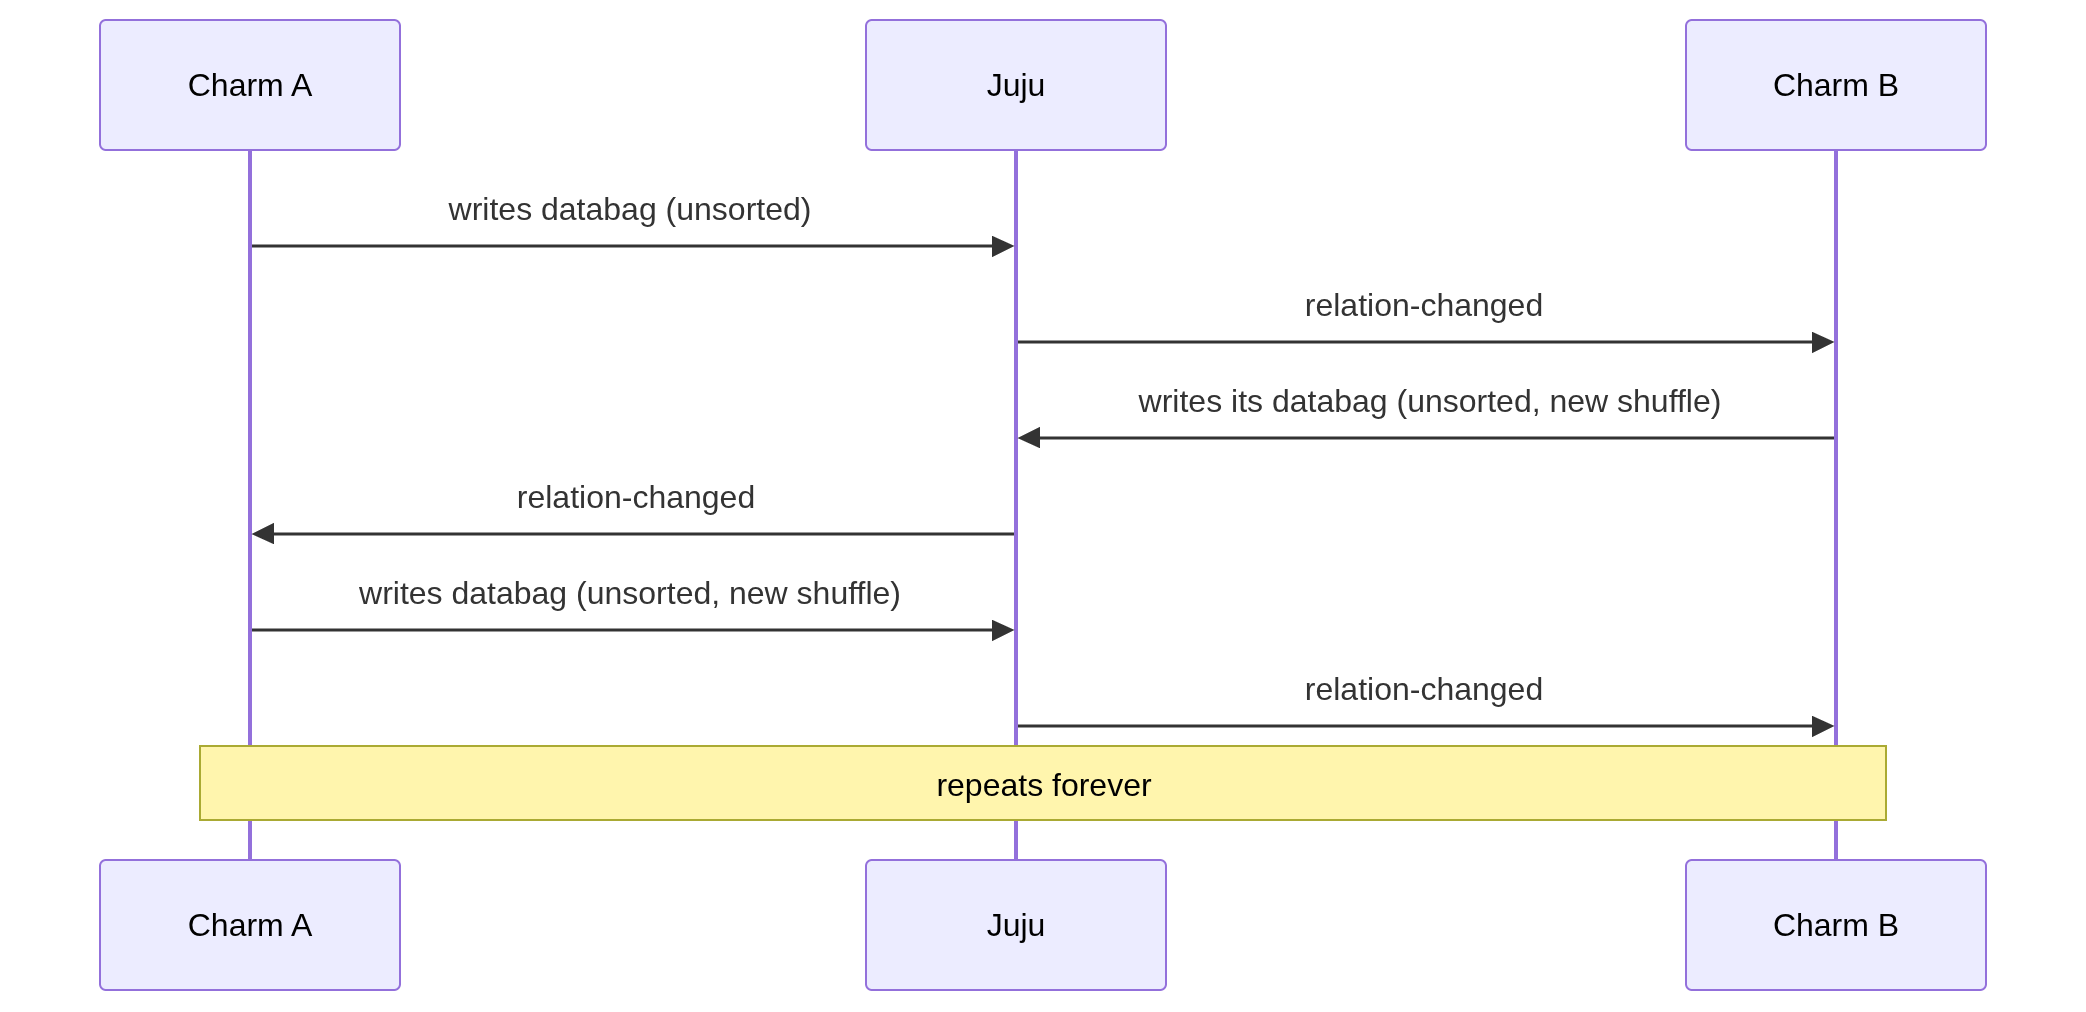
A writes its side unsorted. Juju sees new bytes and wakes B with relation-changed. B reacts by republishing its own side (also unsorted and a different shuffle than last time). That flips A’s view of the relation, which wakes A, which republishes again in a new order… and round it goes.
The tricky bit
Every relation-changed runs your charm’s actual handler code again and if that handler touches a pebble plan or a config file, you might get unnecessary replans and workload restarts on every single flap, which burns hook-execution times and can cause service downtime.
The tricky part is that the unstable value doesn’t necessarily look suspicious where it lands. It’s usually born in one function in one file, then gets passed through a series of assignments, helper calls and returns before it ever reaches relation.data[...] = ... somewhere else entirely. That’s the kind of thing a PR review or a quick read during development can easily miss.
flaplint
I (my opus) wrote flaplint, a static analyser that reads a charm’s source with Python’s ast and traces every value born from an “unstable” source (e.g. set, glob, uuid4, .etc) forward through assignments, function calls, and returns. It follows those values across files, into the charm’s vendored libs, and into installed Python deps that write to a sink, flagging them if they still reach a relation databag, an on-disk file, a pebble plan, or a hash-based change-detector while unstable.
No running deployment needed and no deps to install into your charm. It’s a source read, so it sees every branch, including the ones your tests never exercise.
How to run it
uvx --from git+https://github.com/michaeldmitry/flaplint flaplint /path/to/my-charm/src --own-only
Output from running against canonical/opentelemetry-collector-operator
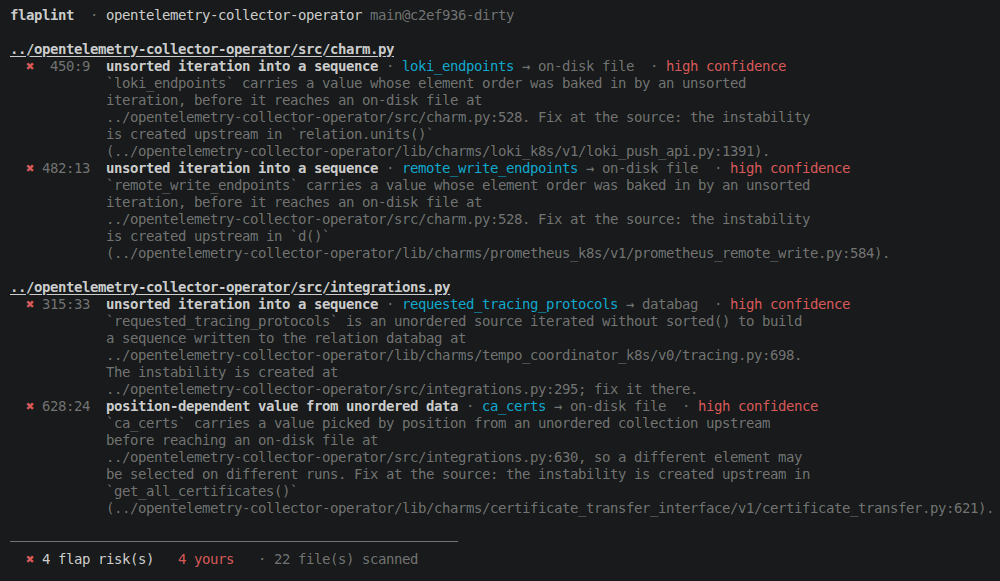
Every one of those four is the value born in the charm’s own code (src/charm.py, src/integrations.py), then followed all the way through a relation library it doesn’t own (loki_push_api.py, prometheus_remote_write.py, tracing.py, certificate_transfer.py) before it’s flagged at the write.
Give it a try
Give it a try on your charms and see what it outputs. I’d love to know what it finds: a real bug, a false positive, or a pattern it doesn’t know about yet, so it gets sharper before it’s worth wiring into CI.